I started this project because I wanted to test the newly introduced Gemma 4 model with Workers AI stack and compare it against my older production-style application built on Next.js + Vercel + Google API (Gemini 3): https://gd.marketscanai.com/en.
I built a production-ready gluten label scanner using Cloudflare Workers + Workers AI, with the @cf/google/gemma-4-26b-a4b-it model for image understanding and structured JSON output. This post explains what we implemented, why Cloudflare was a great fit, how the deployment flow works from local development to GitHub to a live custom domain — and how Workers AI compares to alternatives in the wider AI inference landscape.
ht

What We Built
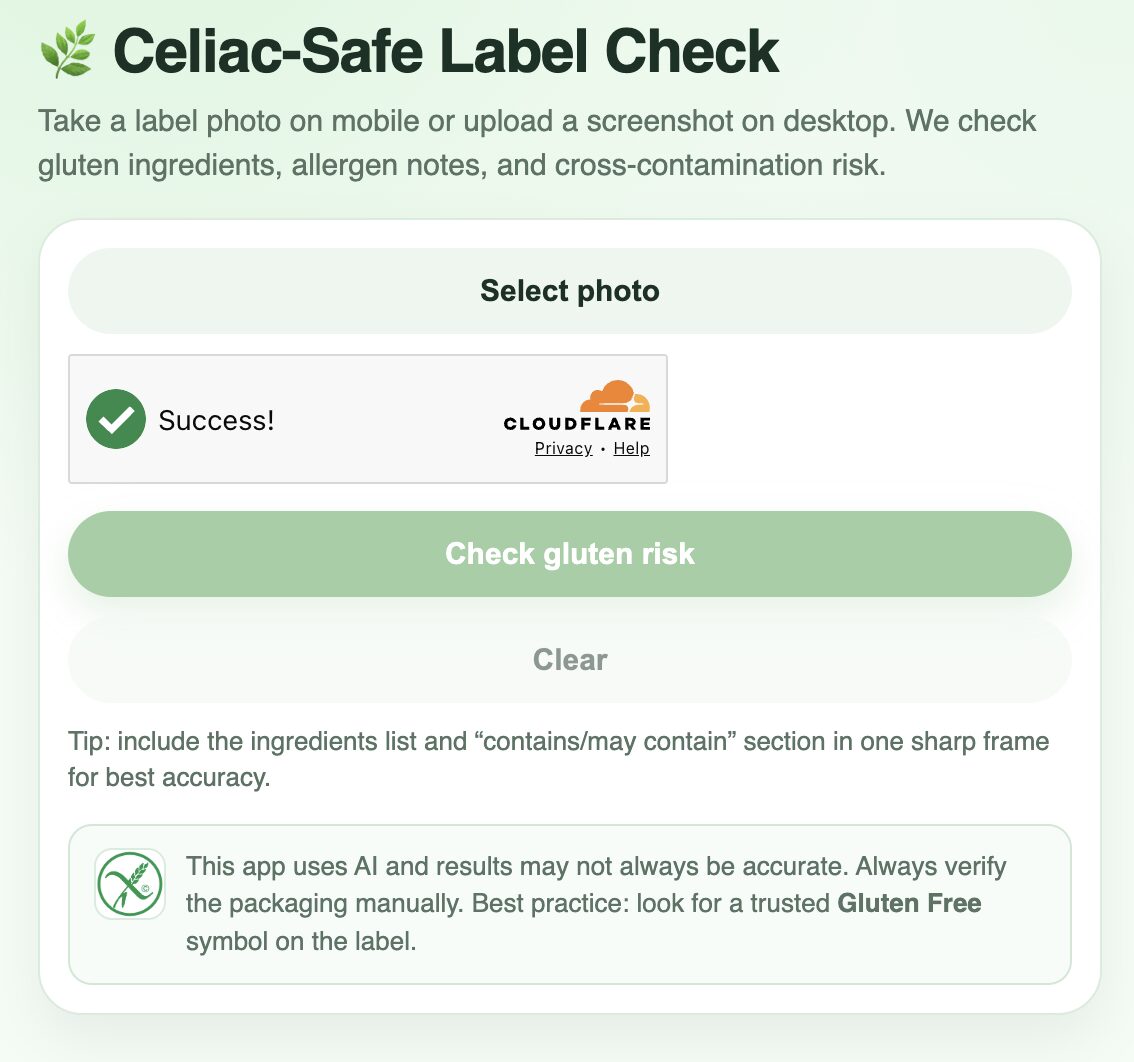
The app lets users upload a product-label photo, then returns:
- gluten risk status (
safe,caution,contains_gluten, etc.) - summary in plain language
- detected ingredients and allergen statements
- cross-contamination notes
- certification presence/absence
The frontend is mobile-first and optimized for one-handed usage — point your phone camera at a product, upload, get an answer in seconds. The backend runs entirely as a Cloudflare Worker endpoint with no separate server or database.
What Is Cloudflare Workers AI?
Workers AI is Cloudflare’s serverless AI inference platform — it lets you run machine learning models directly on Cloudflare’s global GPU network without managing your own infrastructure. You invoke models via a simple env.AI binding inside your Worker, the same way you’d use KV or R2 storage. No containers, no GPU instances, no orchestration layer. developers.cloudflare
Cloudflare has GPUs deployed across more than 150 cities globally, which means your AI inference runs close to your users rather than in a single cloud region. This is a meaningful advantage for real-world applications where latency matters — particularly on mobile.

The platform supports a wide range of task types:
- Text generation / LLMs — Llama 4, Gemma 4, Mistral and others
- Vision / image understanding — multimodal models like Gemma 4 and LLaVA
- Image generation — Flux, Stable Diffusion
- Embeddings — BGE and other models for RAG workflows
- Speech / audio — Whisper for transcription
For this gluten scanner, vision + structured text output was the key capability — and Gemma 4 delivered both in a single model call.
Why Cloudflare Workers AI
Workers AI made this architecture simple:
- no separate GPU infrastructure to manage
- model invocation directly inside the Worker (
env.AIbinding) - low-latency edge runtime with models running globally
- built-in platform tooling (deploys, logs, metrics)
- tight integration with the rest of Cloudflare’s developer platform (KV, R2, Vectorize, AI Gateway)
We used @cf/google/gemma-4-26b-a4b-it with a strict JSON schema so output can be normalized and rendered safely in the UI.
Gemma 4 Integration Details
The API call uses Workers AI with a system prompt + user message containing text + image (data URL):
raw = await (env.AI as any).run(MODEL, input);Why the as any cast?
Gemma 4 is not yet in Wrangler’s generated
AiModelstypes, so the AI call uses anas anycast. This can be removed once Wrangler types includes the model.
In practice, runtime support exists while generated local types may lag behind newest model IDs — a common pattern with fast-moving model catalogs. The model itself (@cf/google/gemma-4-26b-a4b-it) is a 26B parameter Mixture-of-Experts architecture, specifically the instruction-tuned variant, making it strong at following structured output prompts — exactly what we need for consistent JSON responses.
We pass the image as a base64 data URL in the message content and instruct the model to respond with a specific JSON schema:
const input = {
  messages: [
    { role: "system", content: SYSTEM_PROMPT },
    {
      role: "user",
      content: [
        { type: "text", text: "Analyze this product label for gluten." },
        { type: "image_url", image_url: { url: dataUrl } }
      ]
    }
  ]
};
The SYSTEM_PROMPT includes the full expected JSON shape, field descriptions, and explicit instructions to return null for fields that cannot be determined — giving the UI a reliable contract to render against.
Workers AI Ecosystem: More Than Just Inference
One underappreciated aspect of Workers AI is how it integrates with Cloudflare’s broader developer platform. These integrations are worth understanding before committing to the architecture:
AI Gateway
AI Gateway sits in front of your AI calls and adds a control plane layer:
- Unified logging — every request and response logged with token counts, latency, and error details
- Caching — identical prompts return cached responses, cutting inference costs significantly
- Rate limiting — per-IP or global limits on AI calls
- Analytics — request patterns, model performance, cost tracking per endpoint
- Multi-provider routing — route requests to OpenAI, Anthropic, Google, or Workers AI through a single gateway
For a production app, adding AI Gateway takes about 15 minutes and dramatically improves observability. You change one line — point env.AI.run() through your gateway URL instead of directly — and suddenly you have a full audit log of every model call.

Vectorize (Vector Database)
For apps that need semantic search or RAG (Retrieval Augmented Generation), Vectorize is Cloudflare’s native vector database. A gluten scanner could use it to store previously analyzed labels and return cached results for identical or near-identical products, reducing AI inference calls for frequently scanned items. developers.cloudflare
R2 Storage
R2 is Cloudflare’s zero-egress object storage. For a label scanner, this is a natural fit for storing uploaded images — no bandwidth costs for images read by the Worker during analysis.
Cold Starts: A Key Workers Advantage
Cold starts are a known pain point in serverless architectures. AWS Lambda cold starts can reach 100–1000ms; this is unacceptable for interactive AI applications.
Cloudflare Workers use V8 Isolates instead of containers. A new isolate spins up in under 1ms. In late 2025, Cloudflare introduced a “Shard and Conquer” technique using consistent hashing to coalesce Worker traffic onto dedicated shard servers within each datacenter — achieving a 99.99% warm request rate and reducing cold start frequency by 10×.infoq+1
This matters for an AI app: the Worker itself starts instantly. The latency you observe is purely model inference time — not infrastructure spin-up overhead.
Pricing: Neurons Explained
Workers AI uses a unit called Neurons to measure compute consumption. The pricing model is: developers.cloudflare
- Free tier: 10,000 neurons/day (resets at 00:00 UTC)
- Paid tier: $0.011 per 1,000 neurons, with 10,000 neurons/day included
For @cf/google/gemma-4-26b-a4b-it specifically, the cost is: developers.cloudflare
| Direction | Per 1M tokens | Per 1M tokens in Neurons |
|---|---|---|
| Input | $0.100 | 9,091 neurons |
| Output | $0.300 | 27,273 neurons |
This makes Gemma 4 on Workers AI notably cost-efficient compared to calling Google’s Gemini APIs directly — especially for image-heavy workloads where prompt tokens add up quickly. For a typical label scan (medium-length system prompt + image + short output), you’re looking at roughly 1,000–2,000 neurons per request — meaning the free tier comfortably handles around 5–10 scans per day at zero cost.
Always verify current limits before scaling: Workers AI Pricing and Workers AI Limits.
Workers AI vs. Next.js + Vercel + Gemini: A Real Comparison
This project was explicitly built to compare against my existing production app gd.marketscanai.com, which runs on Next.js + Vercel + Google Gemini API. Here’s how they stack up in practice:
| Dimension | Workers AI (this project) | Next.js + Vercel + Gemini |
|---|---|---|
| Deployment model | Single Worker, edge-native | Next.js app, serverless functions |
| AI model | @cf/google/gemma-4-26b-a4b-it (on-platform) | Google Gemini API (external) |
| Cold starts | <1ms (V8 isolates) digitalapplied | ~50–200ms (Vercel Edge) |
| Model availability | Cloudflare’s model catalog | Google’s full Gemini lineup |
| Pricing model | Neurons (usage-based, predictable) | Per-token API calls to Google |
| Vendor lock-in | Cloudflare platform | Vercel + Google APIs |
| Ecosystem | KV, R2, Vectorize, AI Gateway | Vercel KV, Blob, AI SDK |
| Type safety for new models | Lags (requires as any cast) | Depends on Google SDK updates |
| Observability | Built-in dashboard + AI Gateway | Vercel Analytics + external logging |
| Framework flexibility | Worker + any frontend | Full Next.js App Router |
The Workers AI approach wins on infrastructure simplicity and cold-start performance. The Vercel + Gemini approach wins on model capability breadth — Google’s Gemini models (especially Gemini 2.5 Pro) currently outperform open models on complex multimodal reasoning tasks. For a focused use case like gluten label scanning with a tight JSON schema, gemma-4-26b is more than sufficient.
Pros and Cons of Workers AI
✅ Pros
- Zero infrastructure management — no GPU servers, no scaling config, no idle costs
- Edge-native latency — inference runs in 150+ cities, close to users
- Unified platform — AI, storage (KV, R2), vector DB (Vectorize), and gateway in one bill
- No cold starts for the Worker itself — V8 isolates start in <1ms
- Competitive pricing — Gemma 4 at $0.10/M input tokens is cheaper than many hosted API alternatives
- AI Gateway included — caching, logging, rate limiting out of the box
- Hugging Face integration — deploy models from HF in one click
- Free tier is generous — 10,000 neurons/day for prototyping
❌ Cons
- Model catalog is limited — no access to GPT-4o, Claude, or Gemini 2.5 natively (use AI Gateway for routing to external providers)
- Type definitions lag behind model releases — new models require
as anycasts until Wrangler types catch up (as seen with Gemma 4) - Inference latency for large models — a 26B parameter model takes longer per request than a 7B model; not suitable for <500ms SLA requirements on complex images
- No persistent GPU memory — each invocation is stateless; no persistent model context between requests
- Workers CPU limits — the 10ms default compute limit can be tricky for AI SDK integrations
- Ecosystem maturity — Vercel’s AI SDK and Next.js ecosystem is more mature for full-stack AI apps with React Server Components
Bindings Setup
Bindings are the core of the Worker runtime contract:
AIbinding for Workers AI model executionTURNSTILE_SITE_KEYvariable for browser widgetTURNSTILE_SECRET/TURNSTILE_SECRET_KEYsecret for server-side verification
text// wrangler.jsonc (excerpt)
{
  "ai": { "binding": "AI" },
  "vars": {
    "TURNSTILE_SITE_KEY": "your-site-key"
  }
}
Secrets are added separately and never committed to git:
npx wrangler secret put TURNSTILE_SECRET_KEY
Security Notes (Pragmatic)
A key hardening step added near the end was Cloudflare Turnstile:
- Turnstile widget in frontend
- token submitted with each
/analyzerequest - token verified server-side via Cloudflare’s
siteverifyendpoint
This significantly reduces bot and automation abuse on a public endpoint. But Turnstile alone is not the full picture. A layered approach works best for a public AI endpoint — since every unauthorized call costs you Neurons:
- Turnstile verification — filters browser-based bots
- Origin/Referer allowlist in Worker — rejects requests not originating from your domain
- WAF Rate Limiting on
/analyze— e.g. 10 requests/minute per IP via Cloudflare Security → WAF → Rate Limiting Rules - Bot Fight Mode — one-click in Cloudflare Security → Bots panel, available on free plan
The combination makes unauthorized bulk usage expensive and inconvenient without breaking the experience for real users.
Deployment Flow: Local → GitHub → Cloudflare → Domain
1) Local Development with Wrangler
bashnpx wrangler dev
You get a local URL, fast reloads, and direct testing against your Worker logic — including live env.AI calls in development mode.
2) Configure Bindings and Vars
In wrangler.jsonc, configure the ai binding, vars (e.g. site key), and assets directory. Secrets are added via CLI and never committed.
3) Push to GitHub
Commit app code + config + docs. Keep secrets out of git (.dev.vars, .env are gitignored).
4) Deploy to Cloudflare
bashnpx wrangler deploy
This publishes the Worker, updates routes, and applies any binding changes.
5) Attach Custom Domain
Cloudflare routing + domain integration is straightforward. Once the route or custom domain is connected, your Worker serves production traffic directly at your URL — no load balancer, no reverse proxy config needed.
Observability and Metrics
Cloudflare dashboard gives strong visibility for day-to-day operations:
- request counts and HTTP status codes
- runtime errors with stack traces
- logs for debugging API/model failures
- AI Gateway logs: token usage, latency, cached vs. live responses per callapipark
This made debugging and iteration much faster compared to stitching together multiple logging services. With AI Gateway enabled, you also get a cost breakdown per endpoint — useful for understanding which prompts are expensive and where caching would help most.
Project Structure
MVP-style: yes, this app can start as mostly one Worker file plus a few config files.
Current refactored implementation:
src/index.ts— request orchestration and routingsrc/components/render-html.ts— UI HTML/template renderingsrc/lib/gluten-analysis.ts— model config, prompt, parsing and normalizationsrc/lib/turnstile.ts— Turnstile token verificationwrangler.jsonc— bindings, vars, assets configpublic/— static assets (favicon, images)
Still lightweight, but cleanly separated by concern. The total Worker bundle is well under the 10MB script size limit for paid plans.
Interesting Extensions Worth Exploring
Workers AI opens up several directions for enhancing this app:
- RAG with Vectorize — store embeddings of previously analyzed labels; return cached analysis for identical products without calling the model developers.cloudflare
- Streaming responses — Workers AI supports streaming output, so the UI could show analysis results token by token instead of waiting for the full response
- Image generation — use Flux or Stable Diffusion via Workers AI to generate a visual “safe/unsafe” badge image for sharing
- Multi-language output — pass the user’s
Accept-Languageheader and instruct the model to respond in the user’s language, with no backend changes needed - AI Gateway caching — cache responses for identical or near-identical product labels to reduce neuron consumption on repeated scans
Final Takeaways
Cloudflare Workers AI is excellent for shipping practical AI tools quickly:
- simple, unified deployment model
- clean local-to-prod workflow with Wrangler
- good platform observability out of the box
- minimal operational overhead
- genuinely competitive pricing for edge inference
For this gluten scanner use case, it enabled a fast path from prototype to production with a small codebase and clear deployment process. The main trade-off vs. the Vercel + Gemini stack is model flexibility — if you need the absolute best multimodal reasoning, external API calls to Google or Anthropic (routable through AI Gateway) remain an option. But for a focused, structured-output vision task, Gemma 4 on Workers AI is more than capable — and considerably simpler to operate.